RaiderChip’s Edge NPU reaches more than 50 Generative AI Models with the addition of Qwen3.8-27B
The new milestone demonstrates the hardware architecture’s ability to support new generations of AI models without requiring silicon redesign.
Santander, Spain, October 6th, 2026
RaiderChip announces that its GenAI NPU architecture now natively supports more than 50 Generative AI models, with no preprocessing required. The latest additions include Qwen3.8-27B, one of the most acclaimed dense open-source models available today, together with a radically different architecture: the Mixture-of-Experts (MoE) variants of the Qwen 3.5 and 3.6 families, in their 35B-A3B sizes, which activate only 3 billion of their 35 billion parameters for each generated token. This milestone once again demonstrates the NPU’s ability to adapt to the evolution of state-of-the-art models, combining maximum flexibility to support new architectures and models without changes to the underlying silicon and the performance-per-watt efficiency of dedicated hardware specifically optimized for Transformer architectures.
To maximize performance, RaiderChip’s architecture goes beyond accelerating a model: it adapts the execution strategy to each model without requiring any modification to the silicon.
“For each new model, we generate a specific execution strategy through our firmware-based Model Scheduler. The Operation Scheduler Hardware then dynamically distributes the kernels across the available units, maximizing parallelism while consistently maintaining hardware resource utilization above 90% of its physical limit. By optimizing the use of compute resources to the requirements of each specific model, we enable the same hardware platform to behave like an architecture virtually designed to measure, maximizing its performance and efficiency on a model-by-model basis without modifying the silicon,” explains Víctor López, CTO and Principal Engineer of RaiderChip.
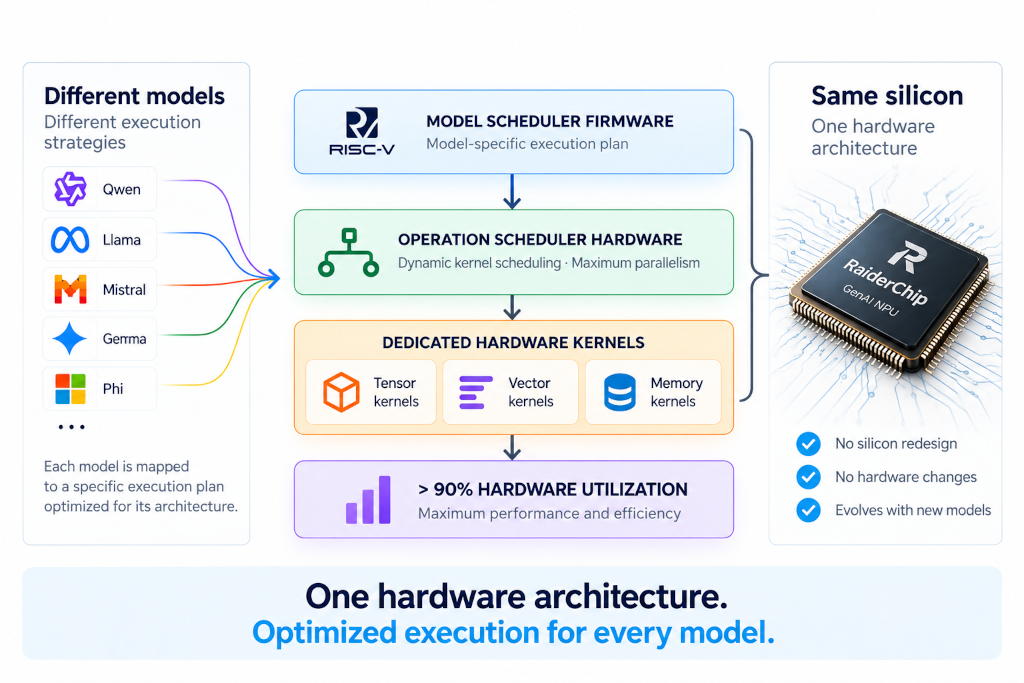
A firmware-generated execution plan tailors the NPU's dedicated hardware kernels to each model, with no changes to the silicon
To make this possible, RaiderChip has developed dedicated hardware kernels for the functional building blocks of Transformer architectures, enabling all model operations to execute directly on dedicated hardware.
The result is a platform capable of delivering two properties that have traditionally been difficult to combine: the behavior of an architecture specifically optimized for each model while, at the same time, retaining the flexibility required to support a virtually unlimited number of Generative AI architectures on an evolvable hardware platform.
With more than 50 models already supported fully natively, RaiderChip consolidates a platform capable of running language, reasoning, vision and audio models, as well as robotics policies, concurrently on the same architecture.
An NPU designed to evolve with future generations of models.
WANT TO KNOW MORE?
Learn more about RaiderChip’s NPU
ABOUT RAIDERCHIP
RaiderChip is a fabless semiconductor company specializing in the design and commercialization of acceleration solutions for Generative AI, both through its own devices and by licensing its architecture as IP for integration into third-party ASICs.
Its technology enables advanced AI models to run locally, combining high performance, energy efficiency, privacy, and flexibility to bring capabilities currently associated with data centers directly to edge devices and systems.